RunPod integration

We connected the application to RunPod, a GPU cloud platform. Requests from the product can reach GPU-backed inference.
Client project · Delivered. We connected TenDev's AI workloads to dedicated GPU infrastructure and engineered the deployment path around real application traffic.
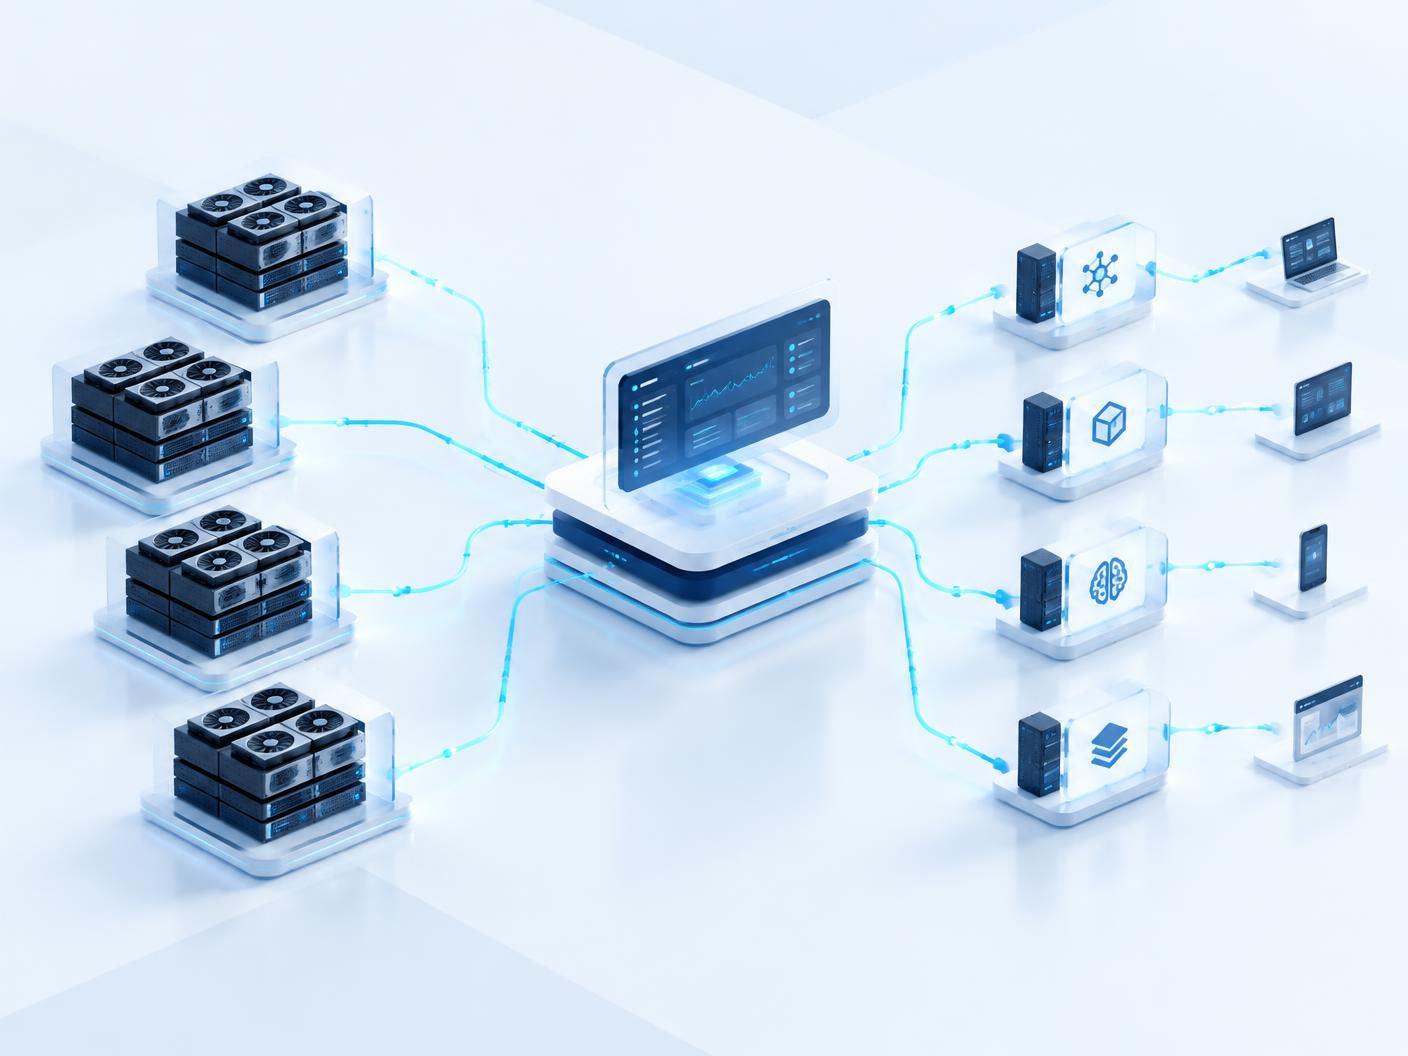
The work centered on RunPod integration: connecting application requests to GPU-backed inference while keeping deployment behavior predictable and observable.
We implemented the deployment path around the model endpoint, including the application-facing connection and the operational behavior needed outside a prototype.
We connected the application to RunPod, a GPU cloud platform. Requests from the product can reach GPU-backed inference.
The AI workloads were deployed onto dedicated GPU infrastructure. Deployment behavior was kept predictable and observable, as production use requires.

We implemented the application-facing connection to the model endpoint. The product calls the AI capability like any other service.
The work covered the operational behavior needed outside a prototype. The result runs as part of the product, not as a separate demo.
The result is not a standalone model demo. It is an integrated AI capability that can be called from TenDev's product workflow.
Many AI projects stall between a working model and a working product. Closing that gap is mostly integration and deployment engineering. That is the core of our AI integration work.
Tell us where the model runs today and how the product needs to call it. We'll look at the integration and deployment path.
Walk us through a process